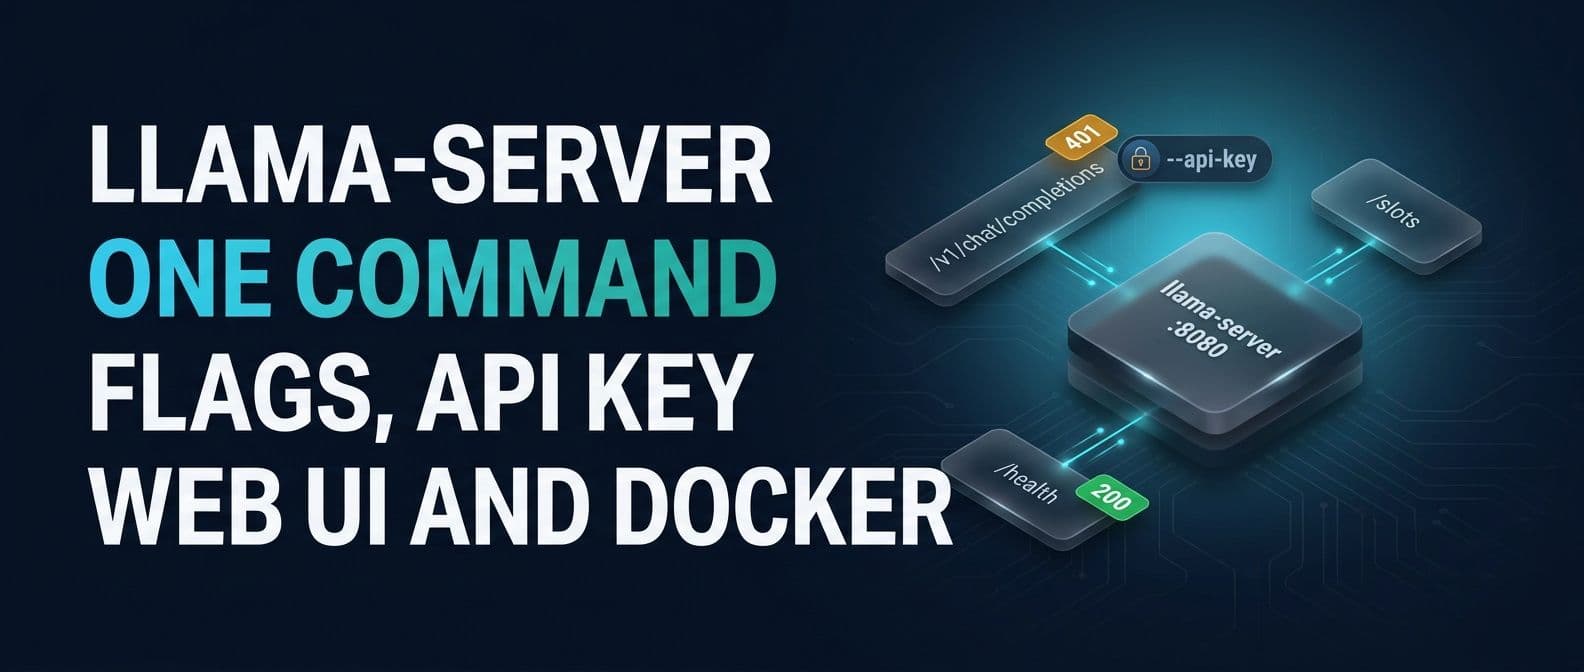
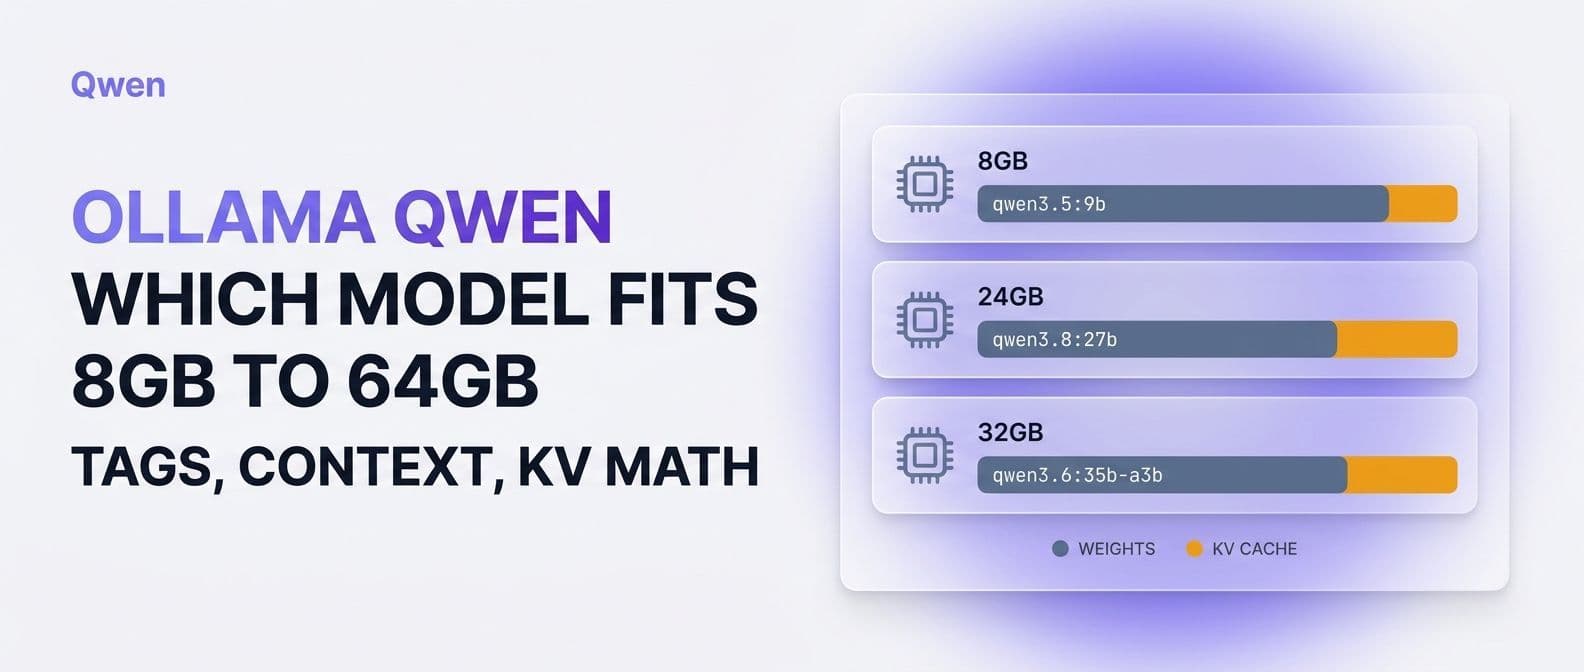
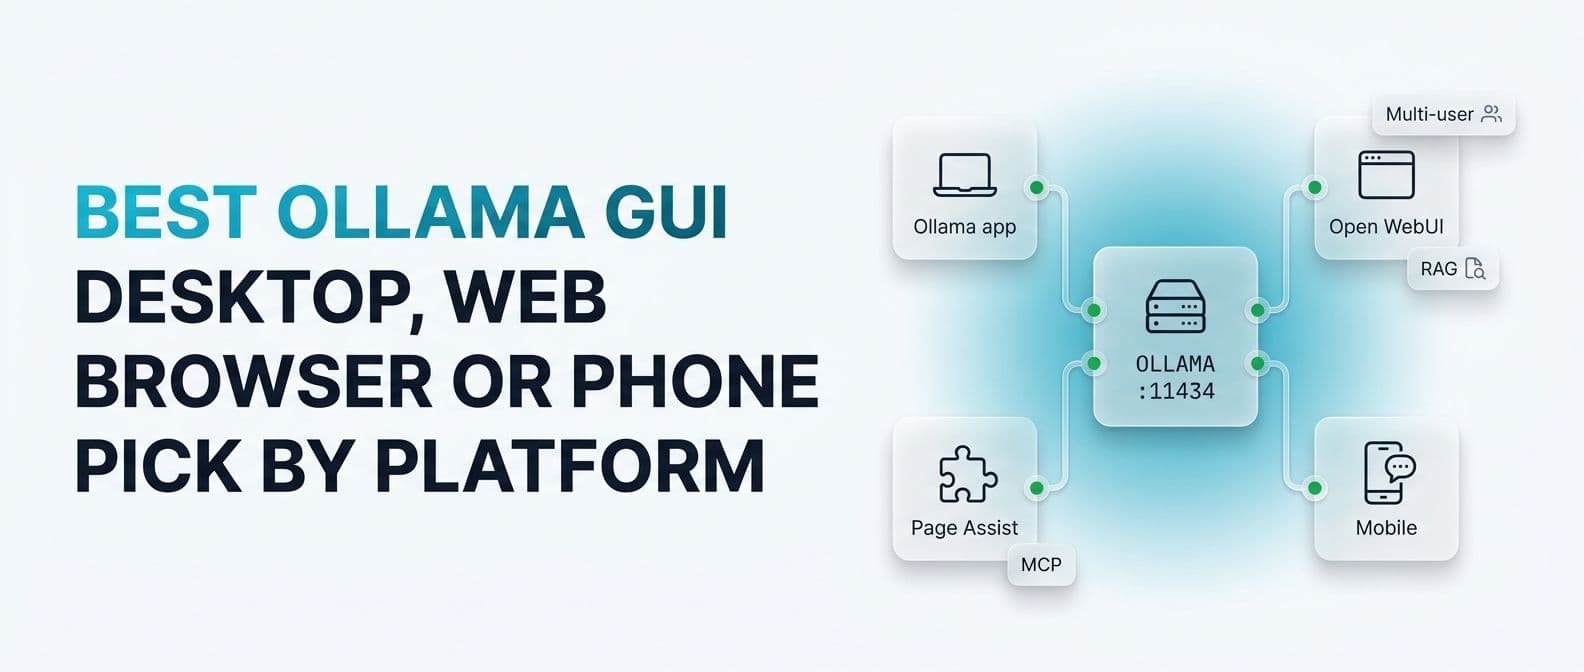
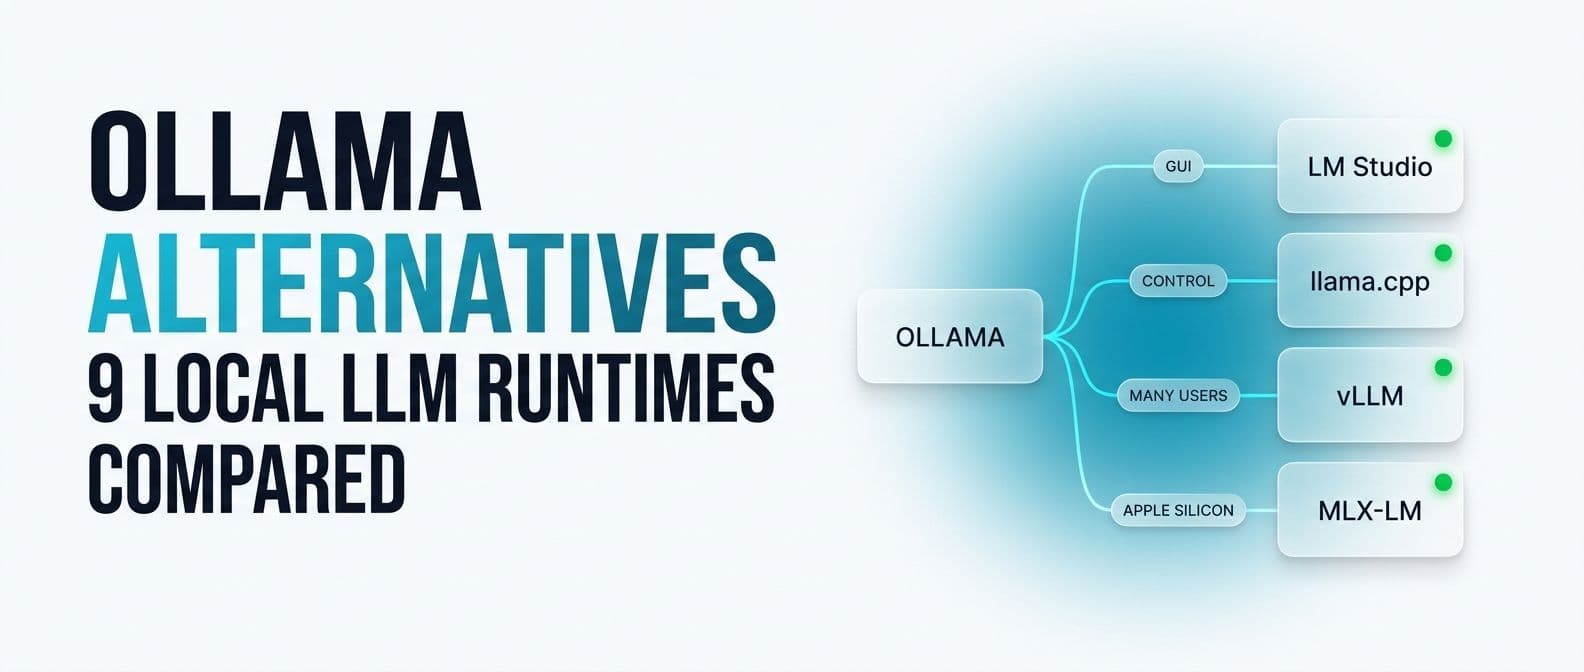
Running models on your own hardware: Ollama, llama.cpp, quantization, front-ends, and memory sizing.
Agent SDKs, MCP servers and debugging tools, and code sandboxes, compared and tested.
Tracing and evaluation tools, vector databases, and what LLM workloads cost to run.
Tested guides and calculators, with the commands, versions and numbers to reproduce them.